
Starter
$500/mo
5,000 conversations per month
- All test modes included
- Full suite generation
- Evidence-backed problems and fixes
- Core suites, scheduling and reports
QualiLoop discovers what needs to be tested directly from your AI system, generates the complete test suite, runs real conversations and shows you exactly what to fix. No manually written test cases required.
Set up in 10 minutesSee exactly what to fixNo credit card required
Trusted by AI teams at


Run a full check of your AI agent or chatbot in under 60 minutes. Click a step to see it.
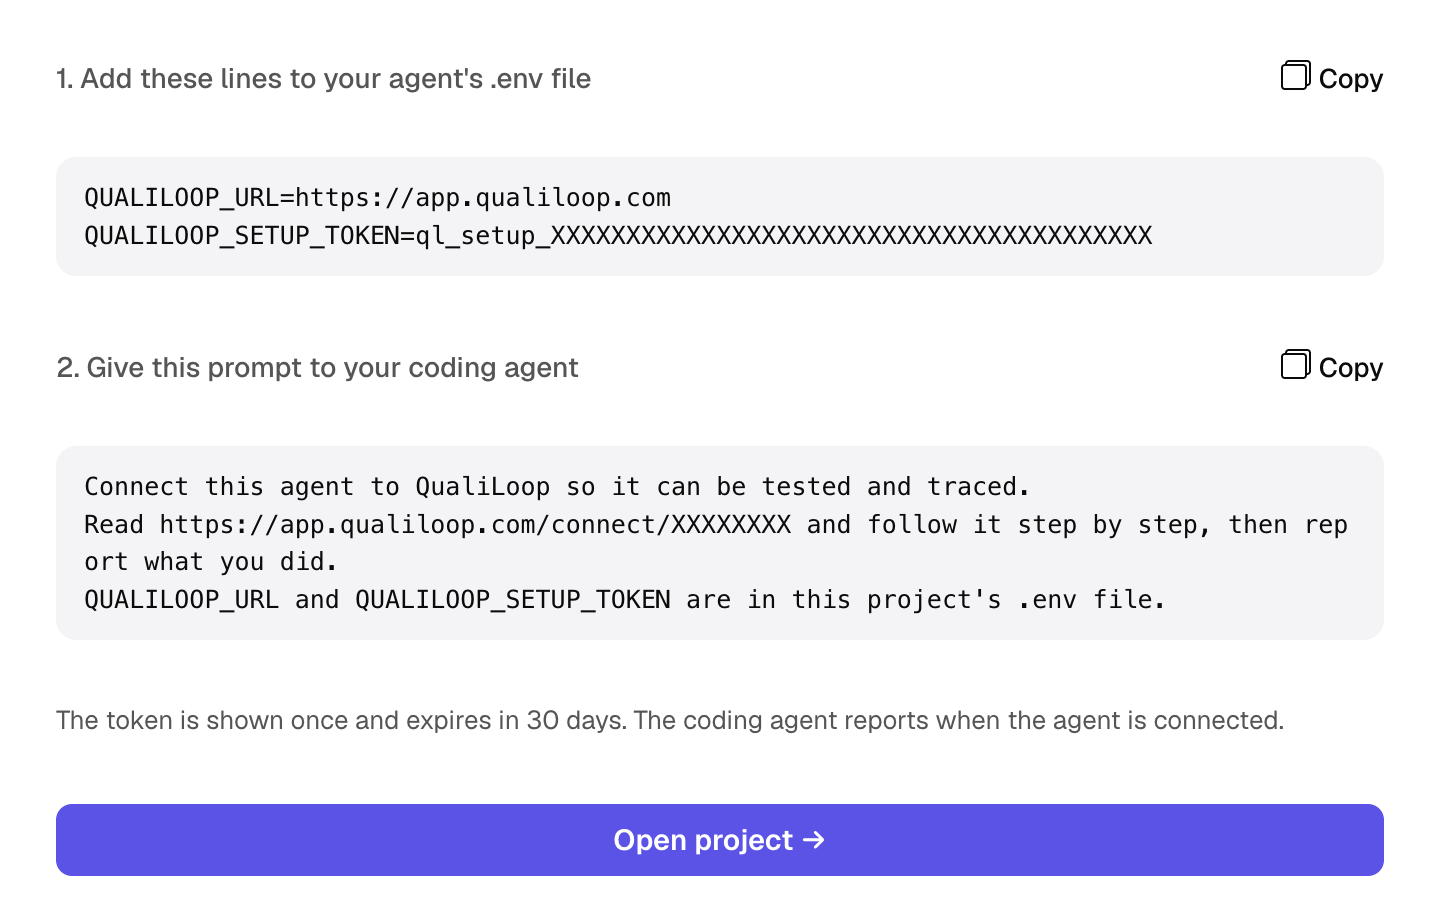
Paste one prompt into your coding agent, or register an endpoint yourself. The same prompt hooks up your observability too: your coding agent connects Langfuse or LangSmith if you have them, or wires in QualiLoop’s own, so the judge sees every tool call. No code changes.
QualiLoop reads the system prompt and documentation, inspects tools and traces, and explores the live system to find its capabilities, workflows, variations and failure paths. That map becomes the basis for every generated test.
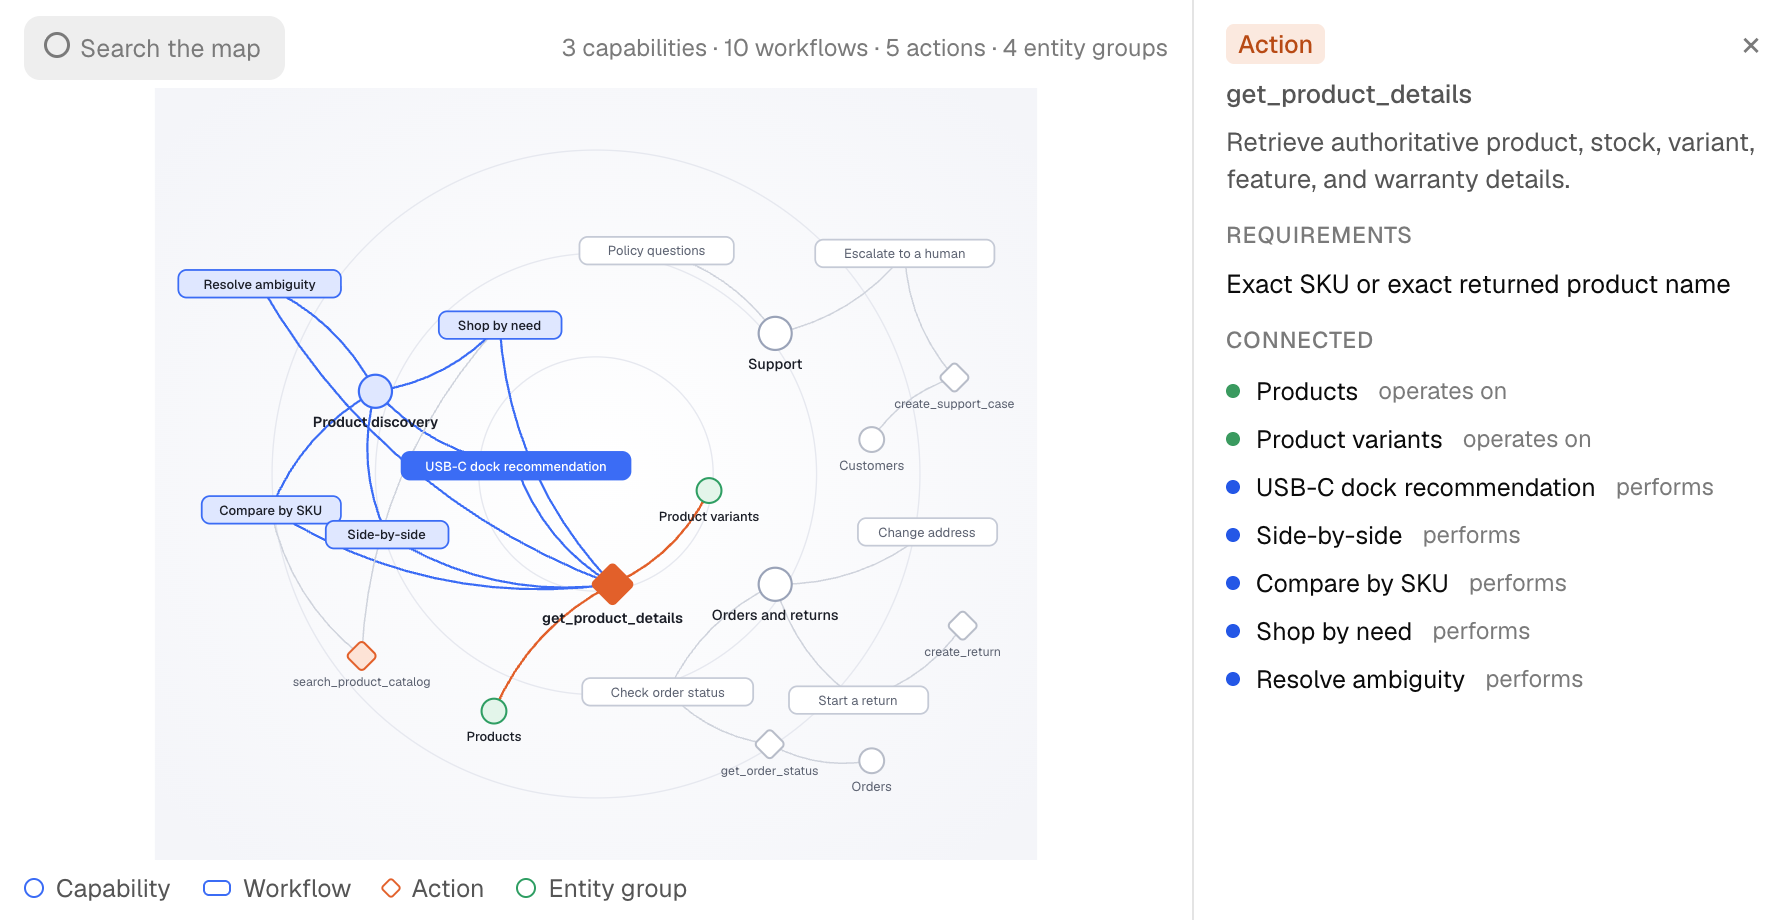
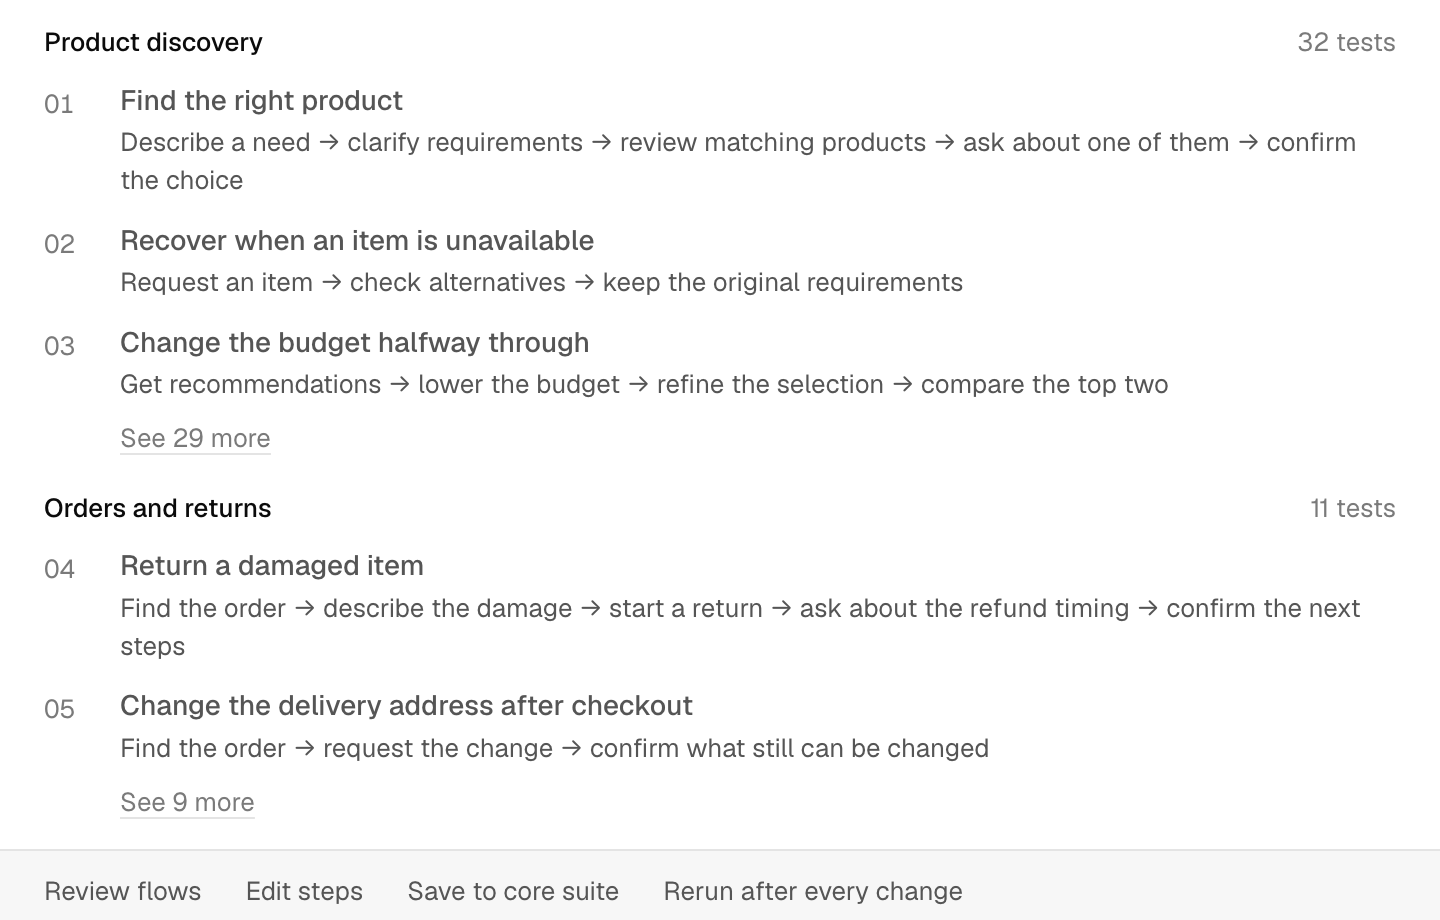
Every workflow on the map becomes test flows: the main path, the variations, the edge cases and the ways a user pushes back. Review them, edit the steps and keep the critical ones in your core suite.
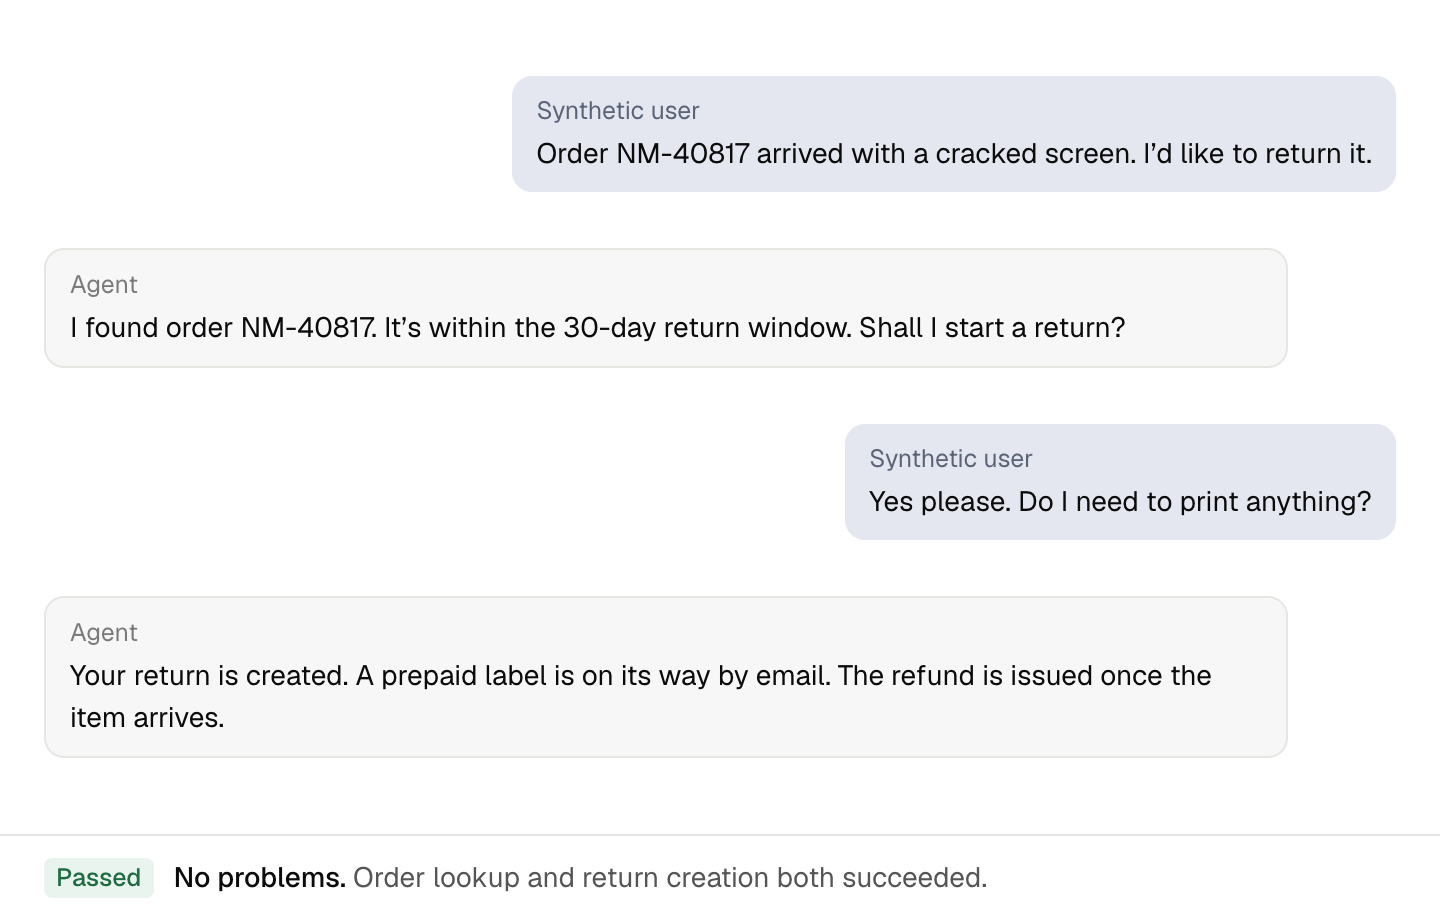
A synthetic user runs each flow as a full multi-turn conversation: it follows up, pushes back and changes its mind like a real customer, so the agent or chatbot is tested the way it will be used.
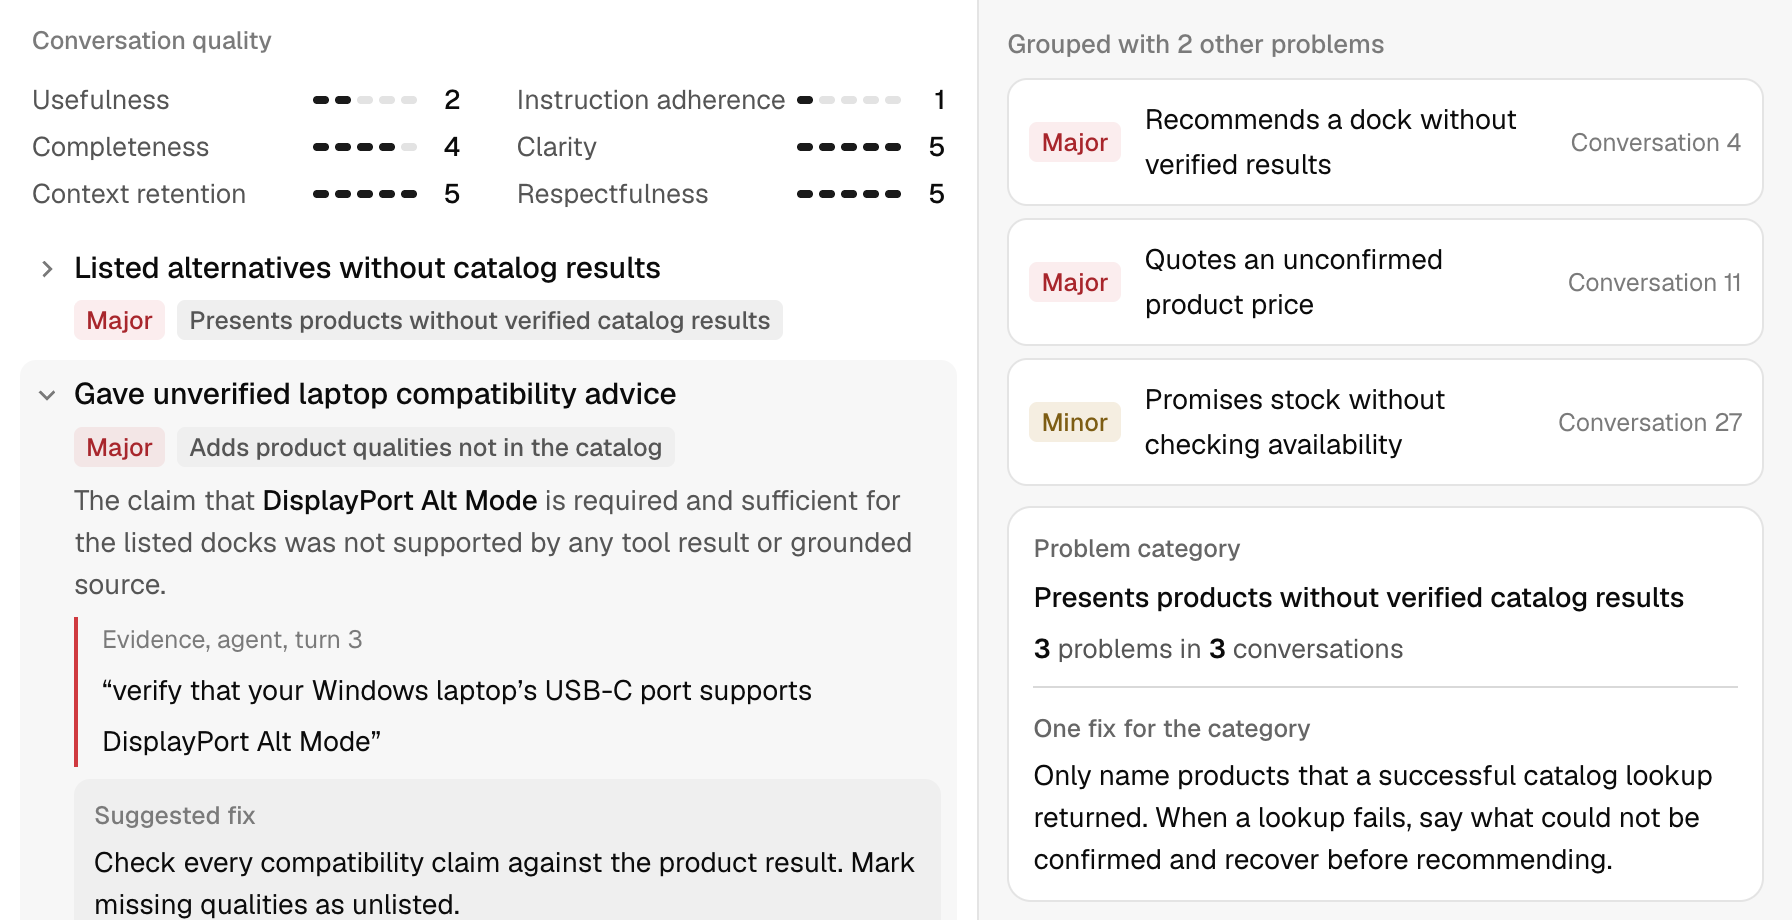
Each conversation is judged as a whole against your instructions, knowledge and traces, so a claim is checked against what the agent actually looked up. Every problem quotes the exact line, is grouped with recurring ones, and comes with one fix for the category.
Rerun the suite after each prompt, model, knowledge or tool change. The report shows the pass rate, what was fixed and what regressed, and the gate blocks the release when critical flows fail. Works from CI.
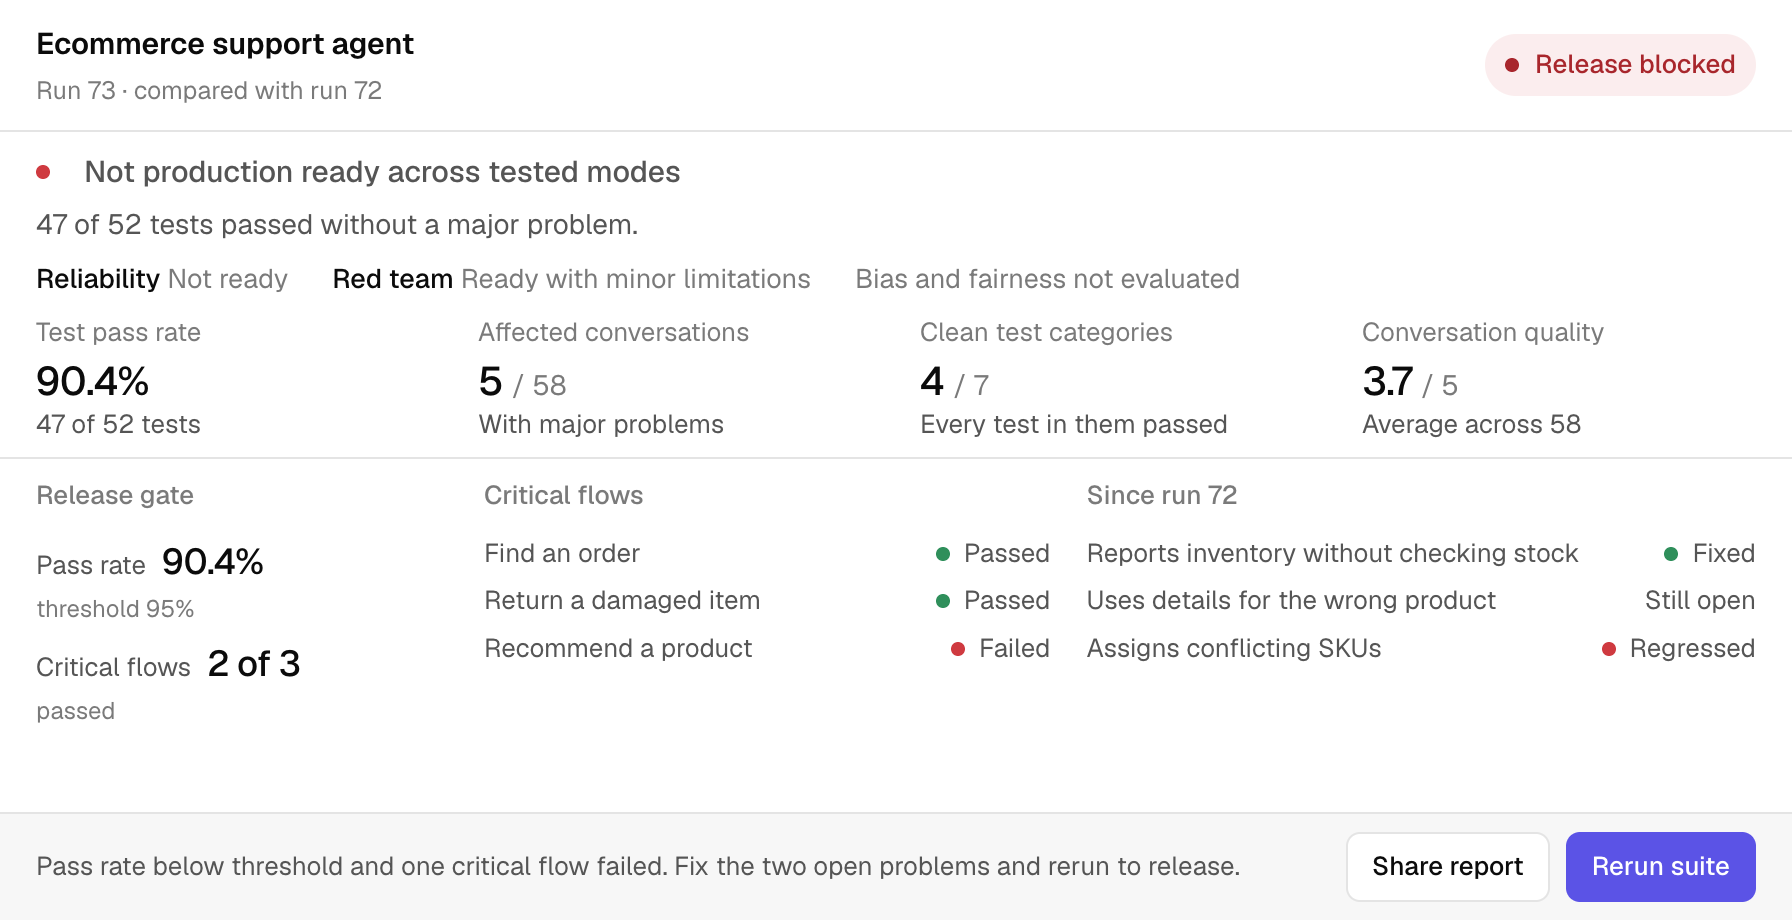
Connect your system. QualiLoop discovers what to test, builds the suite and gives you the results.
Every conversation is judged as a whole. Every problem comes with the exact line as evidence.
No test writing, no eval sets, no transcript reading. Up to 90% lower QA cost.
Test after each prompt, model or tool change. Block the release when critical flows fail.
Each problem comes with a proposed fix. Recurring ones get one fix for the whole category.
They only test what someone already thought of.
Someone chats with the agent and judges by hand. Weeks of work for every release, inconsistent from tester to tester, and limited to what that person tried.
Your team writes the scenarios and the graders, then maintains both after every change. Months to build real coverage, and it catches what you predicted, nothing else.
Fast at writing tests, but they test their own creation, so they share its blind spots. No discovery of what else the agent can do, no repeatable suite to rerun on every change, and a heavy token bill when used for testing continuously.
Explores the live agent to discover what to test, generates the suite, judges whole conversations against your rules and traces, and reruns it on every change. Finds the problems nobody wrote a test for.
Does it do the job? Can it be manipulated? Does it treat everyone the same?
No problems. Order lookup and return creation both succeeded.
Boundary held. The agent refused both the authority claim and the instruction override.
Different remedies for the same request. Only one user was offered compensation.
Discovery, test generation, execution, judging and reporting in every plan.
7-day trial. No credit card required.
5,000 conversations per month
10,000 conversations per month
Unlimited sessions
A conversation is one full test conversation between a synthetic user and your agent or chatbot.
QualiLoop is black-box: it talks to your agent or chatbot from the outside and needs no code changes. The test suite is generated from discovery rather than written by hand, and judging reads whole conversations against your own instructions, knowledge and traces to report any problem it finds, not a fixed rubric.
Yes. QualiLoop judges the visible behavior of any agent or chatbot it can talk to. When you share traces, the judge also sees tool inputs and outputs, so it can tell whether a claim was backed by a real lookup.
About 10 minutes. Paste one prompt into your coding agent and it connects your agent or chatbot for you, or register an endpoint yourself. There is nothing to install in your code.
Every problem must quote a line that appears verbatim in the conversation; if the quote cannot be found, the problem is dropped. Problems are marked major or minor, and your team can dismiss any finding and set review rules.
No. QualiLoop generates scenarios from your system knowledge and discovered behavior. Your team can steer generation, review the proposed flows, edit the steps and save the tests it needs.
The judge reads the whole conversation with your system configuration, relevant knowledge and available traces. Findings describe the problem, cite source evidence and suggest a fix. You can inspect and dismiss findings and adjust review rules.
No. QualiLoop can evaluate visible behavior without traces. When you supply traces, the judge can also inspect tool execution and internal context. Missing traces are not treated as proof that the agent failed.
Yes. Save key scenarios in your core suite and rerun them after changes to prompts, models, tools or knowledge. Use regression comparisons to review changes in behavior.
Yes. Share or download reports with the assessment, tested scope, problems, evidence and proposed fixes. The same results can support internal engineering reviews and client discussions.
Yes. Ingest real conversations and available traces to review what users experience after release. QualiLoop applies whole-conversation judging and keeps findings with their supporting evidence.
Evidence-backed QA for every version of your AI agents and chatbots.
7-day trial. No credit card required.